Everything on your Docker hosts, from a browser and a terminal
One container. A web dashboard, a keyboard-driven TUI and a scriptable CLI, all clients of the same core. No agent on your hosts, no orchestrator, no database server, no SaaS account.Deploy a Compose stack, undo a bad one, follow the logs, drop into a shell, see which images carry CVEs, and do it across every server that joined the cluster. Or hand the same server to an AI agent over MCP, on the same port.
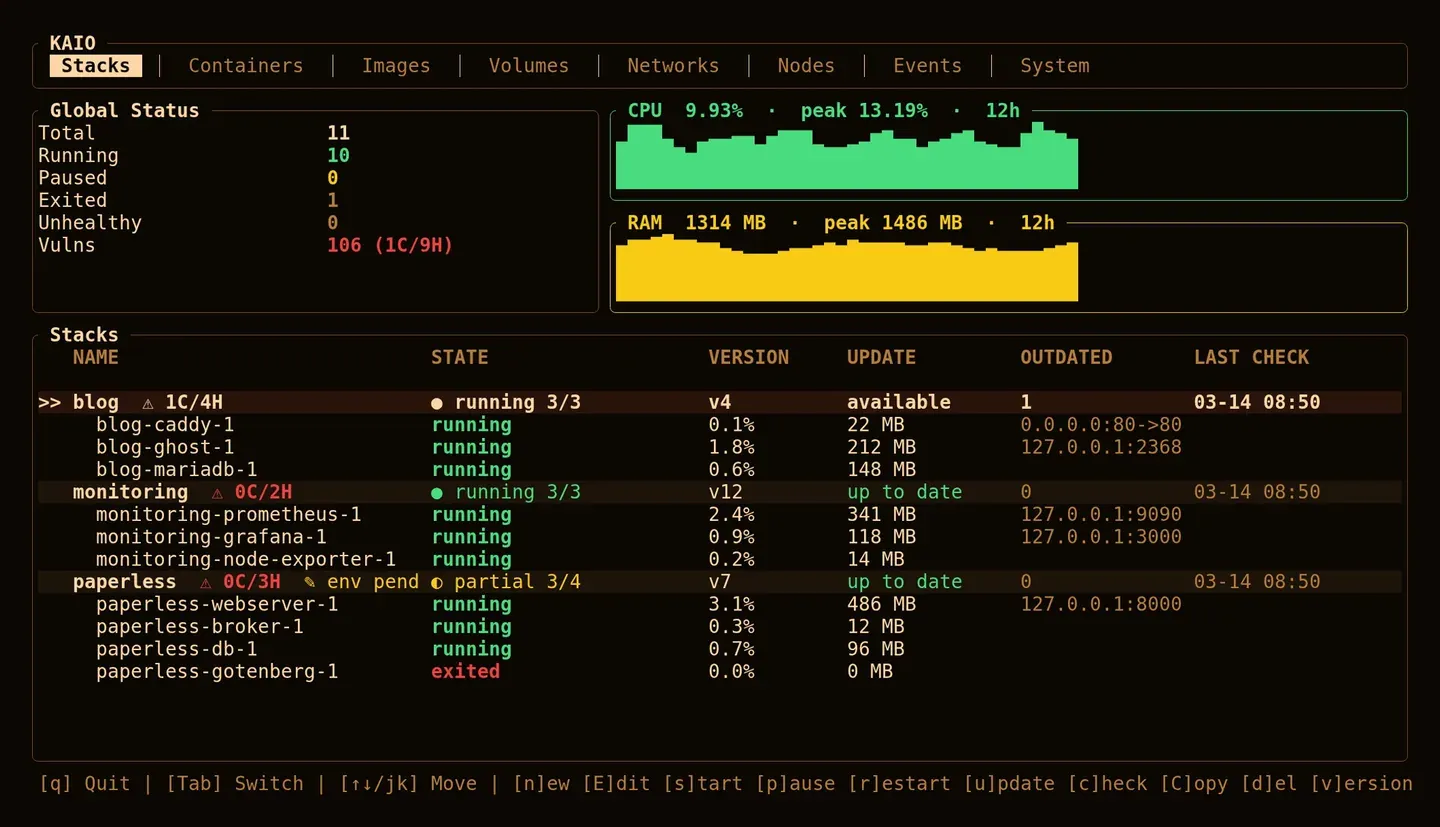
The dashboard above is one client. This is another, on the machine itself, with
no browser and no port to forward: kaio-cli tui. Same stacks, same versions,
same CVE counts, computed once by the same server. Create a stack, write its
compose.yml in your own $EDITOR, add a variable and deploy, all under Tab
and a handful of keys.
Every tab under [Tab], then a stack created end to end: name it, write its compose.yml in $EDITOR, add a variable, deploy.
No agent, no daemon of ours, no sidecar. Run Kaio on a host and it already
manages it; run it on a second and let them join: kaio-cli join enrols
a machine with no address typed by hand, and cluster leave takes it back
out from the machine itself. A server that changes address is recognised,
not duplicated. The API a node already serves is the protocol, so there is
no second thing to keep upgraded, and nothing new listening on your servers.
Three interfaces, one truth
Click it in the browser, drive it from the TUI over SSH, script it in CI
with --json. All three are clients of the same server, which computes
every number once, so nothing can disagree with anything else. There is no
second implementation to drift.
Move a stack, data and all
Copy a stack to another server with its variables, its whole version
history and the contents of its volumes, streamed through the control plane
so the two hosts never need to reach each other. The source is never
stopped, written to or removed, and a copy that fails undoes itself. A copy
that could never start, because a port is taken, is refused rather than
written.
A pipeline is a first-class client
The CLI is a thin HTTP client: no checkout of Kaio, no toolchain, no
Docker socket in the runner. Three lines are a deploy that verifies
itself: health refuses a server that is down before anything is written,
stack deploy blog compose.yml --env-file .env.ci writes it, and a
--json status check reads the containers back. A 0 from the deploy only
means it was accepted, so that last step is what fails the build when they
did not stay up. A failed compose up has already restored the previous
version by then, so a bad commit leaves the last working stack running.
Every command speaks JSON
--json turns the CLI into a data source, so a pipeline gates on what the
server already knows rather than on scraped output: jq -e over status
when the containers did not stay up, over image ls when a scan found a
critical CVE, over node ls when a server stopped answering. The same
node ls rolls one deploy across every server that answered.
A protocol for your agent, not a chat box
Kaio speaks the Model Context Protocol at /mcp, on the same port as
everything else. Point an agent at it and “why is the media stack partial”
is answered from the same numbers the dashboard shows, not from scraped
output. The endpoint is off by default, and KAIO_MCP is a ladder:
read where no tool can change a thing, write for deploys and copies,
admin for what has no undo. An agent only sees the tools its rung allows.
Graph it in Grafana, if you want to
An option, not a dependency: Kaio draws its own charts and keeps a day of
them. Turn on KAIO_METRICS and it also speaks Prometheus at
/metrics, on the same port as everything else, so Grafana keeps the
history Kaio deliberately does not. A scrape costs no call to the Docker
daemon, your fleet names itself because one Kaio hands Prometheus the rest
of the cluster, and make metrics-full-run stands the whole thing up, Kaio
included, with the dashboard already loaded.
Alerted on what only Kaio knows
A dashboard helps while you are looking at it. The reason to scrape Kaio is
not another CPU graph, it is Alertmanager waking you over state nothing
else on the host can see: a stack partial for ten minutes, an image
update waiting a week, a critical CVE that appeared overnight on an
image you built in March, variables saved and never applied, a server that
stopped answering its peers. Nine rules ship written. One of them watches
Kaio itself, and fires when it stops reading the daemon while still happily
serving pages.
Nothing is held back
No paid tier, no seat count, no node limit, no feature waiting behind a
sales call. CVE scanning, the cluster, the gateway, the MCP endpoint: what
you read on this page is what one container gives you, on the first host
and on the twentieth.
Your files stay your files
A stack is a directory on the host: compose.yml next to its .env, where
plain docker compose still works on them. Nothing is locked inside a
database, so removing Kaio leaves your stacks running. SQLite keeps the
history, and data/ is the one thing worth backing up.
Today's CVE, on last year's image
Trivy runs as a throwaway container, so there is nothing to install. In-use
images are rescanned on a schedule you choose, starting at boot. A
vulnerability disclosed this morning surfaces on an image you built months
ago, without anyone running a command.
Change a variable without holding your breath
A stack’s variables live in a .env at mode 0600 next to its compose
file. Names that look like one (*_PASSWORD, *_TOKEN, *_KEY) are
flagged secret on their own: reading them back gives null, and leaving
one empty keeps the stored value, so you never retype a password to change
a tag. From the CLI or the TUI an edit is saved as pending until you
apply it, so you pick the moment containers restart. And a failed
compose up puts back the previous compose.ymland the previous
.env together: a bad variable is an undo, not an outage.
Undo, not regret
Every deploy is a numbered version: the compose file and its variables,
captured together. Roll back and both come back as a pair. A failed
compose up restores the previous one on its own, so editing a live stack is
an undo away, not a gamble.
One fleet, one dashboard
From your entry point, list every server that answered, in the web UI under
Manage → Nodes, in the TUI’s Nodes tab, or with kaio-cli node ls.
Then drive any of them by name: kaio-cli node web-01 run stack deploy api ./compose.yml. Removing a node closes that path, while its own address
stays exactly as reachable as before.
Catches a moving latest tag
The checker asks the registry for the manifest digest and compares it with
what you are actually running, so a rebuilt latest is caught where a
version string would lie. Nothing is pulled, and nothing is recreated,
until you say so.
From a spike to a shell
Live CPU, memory and network per container, summed per stack. When a number
looks wrong, stream the whole stack’s logs merged by service, then open an
interactive shell inside the container, without leaving the page.
Kaio does not build images from a git repository, run a reverse proxy, issue
certificates, turn a database into a managed resource of its own, or decide
which host a workload lands on. A PaaS owns all of that, and owning it means
choosing it for you: its builder, its proxy, its certificate flow, its database
images and the way they are backed up.
Kaio leaves each of those open. Build in the CI you already run and deploy the
tag it pushed. Front it with nginx, Caddy, Traefik or none of them. Run
Postgres, MariaDB or Redis as a stack like any other, on their own images and
your own volumes, or keep pointing at the server you already have. Because a
stack stays an ordinary Compose project on disk, the tools you already use keep
working on it, and the ones you pick next will too.
Kaio has no authentication: whatever reaches its port controls the Docker
daemon, which is root-equivalent on that host. A permissive CORS policy means your
own browser is part of that reach. So it is built to sit
behind whatever you already trust: a reverse proxy with basic auth, an SSO
gateway, a VPN or a mesh network, or nothing at all on a host only you can
reach. It expects to be the thing behind the door, not the door.
Bind it to 127.0.0.1, put your own layer in front, and read
Security for what that layer needs to cover.